ART: Automatic multi-step reasoning and tool use
Task library, program flow, pause/resume and successful-example writeback.
Paper information
| Field | Details |
|---|---|
| Paper | Paper or original source |
| Institution | University of Washington / UC Irvine / Meta AI. |
| First public release | 2023-03-16 |
| Author code | bhargaviparanjape/language-programmes. |
| Local adapter or method key | art |
| Local reproduction code | src/auto_research/agent_research/ |
Paper method and evidence
Retrieve relevant reasoning/tool examples automatically. A frozen LLM produces a program; generation pauses at tool markers and resumes after injecting results. Humans can expand the library with a few corrections.
flowchart LR
  A[Retrieve examples] --> B[Generate program flow]
  B[Generate program flow] --> C[Pause for tools and resume]
  C[Pause for tools and resume] --> D[Update task library]
Original paper figure
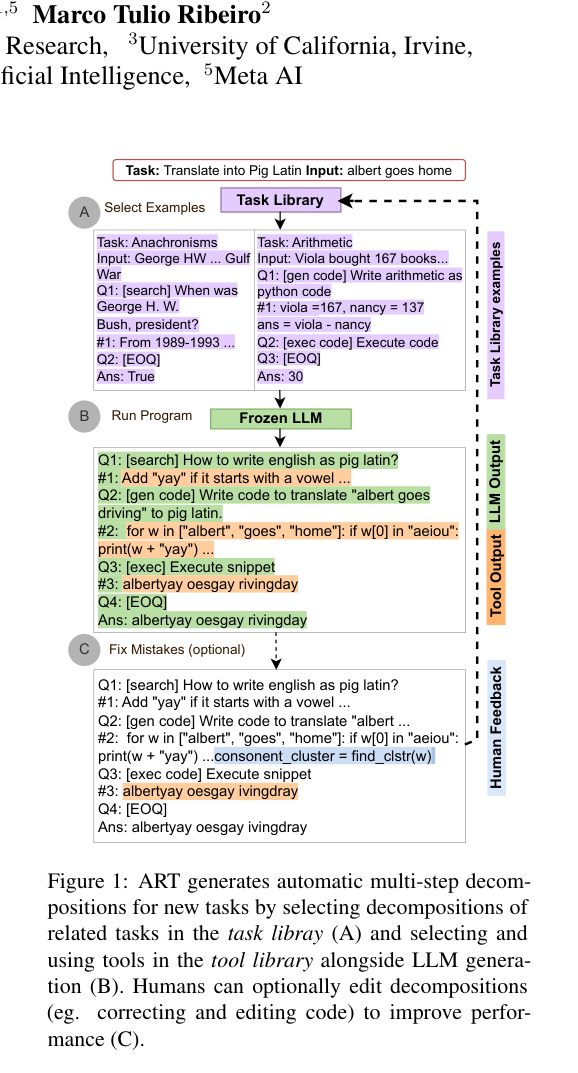
The original figure shows library and program execution. From the original paper; copyright remains with the authors.
Core equation
Reported results
On unseen BIG-Bench/MMLU tasks ART beats few-shot and automatic CoT, reaching handwritten-CoT quality on most tasks; correcting five faulty programs per task improves results. No production A/B.
Local reproduction
PlanBench mini 120 episodes, seed 42; library indexed by tool signature. Baseline vs ART: joint success 1.0000/1.0000, mean cost 64.5000/1.5500, examples 0/108, pauses/library updates 0/0 vs 360/12. Metrics. Tiny library, no frozen LLM or BIG-Bench/MMLU results.