Tree of Thoughts
Thought branching, BFS beam selection, value evaluation and backtracking; not single-chain CoT.
Paper information
| Field | Details |
|---|---|
| Paper | Tree of Thoughts: Deliberate Problem Solving with Large Language Models |
| Institution | Princeton University / Google DeepMind. |
| First public release | 2023-05-17 |
| Author code | princeton-nlp/tree-of-thought-llm. |
| Local adapter or method key | tree-of-thoughts |
| Local reproduction code | src/auto_research/agent_research/ |
Paper method and evidence
Treat intermediate thoughts as independently evaluable units. Expand multiple candidates, score the frontier with an LM value function, and search BFS or DFS with lookahead and backtracking instead of committing to one chain.
flowchart LR
  S[Thought frontier] --> E[Expand alternatives]
  E --> V[Evaluate thoughts]
  V --> B[Prune BFS beam]
  B --> S
  B --> R[Backtrack if needed]
Original paper figure
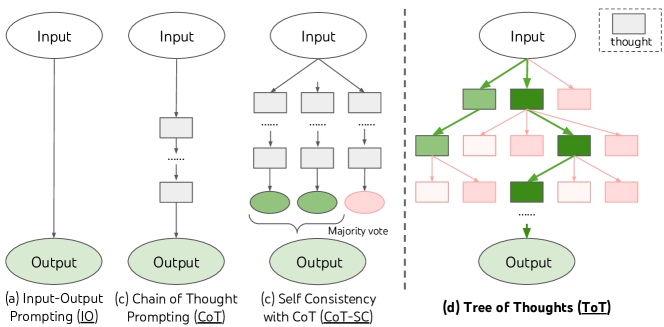
The original figure contrasts thought-search strategies. From the original paper; copyright remains with the authors.
Core equation
Reported results
With GPT-4 on Game of 24, CoT succeeds 4% and ToT 74%. The paper also tests creative writing and mini crosswords; no production A/B.
Local reproduction
auto-research agent-eval --method tree-of-thoughts \
  --benchmark planbench-mini --episodes 120 --seed 42
PlanBench mini expands correct and distracting action thoughts layerwise using deterministic workflow coherence and beam width 2. Joint success 1.0000, mean cost 2.5000, expanded nodes/backtracks 1200 / 480. Stable metrics. No GPT-4 self-evaluation or Game of 24; the perfect score verifies search mechanics only.