ToolBench / ToolLLM
Fidelity: core mechanism. The deterministic mini-suite does not stand in for the paper's full benchmark.
Paper information
| Field | Details |
|---|---|
| Paper | ToolBench / ToolLLM (arXiv 2305.16504) |
| Organization | Tsinghua University |
| First public release | 2023-05-25 (arXiv v1) |
| Authors' code | No official code repository from the authors was found. |
| Adapter / method | toolbench |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
After analyzing tool failures in open-source LLMs, the method combines programmatic usage examples, a system prompt, retrieval of in-context demonstrations, and output-format constraints.
flowchart LR
 A["Public inputs"] --> B["ToolBench core mechanism"]
 B --> C["Matched-budget training or execution"]
 C --> D["Public evaluation and diagnostics"]
Key figure from the paper
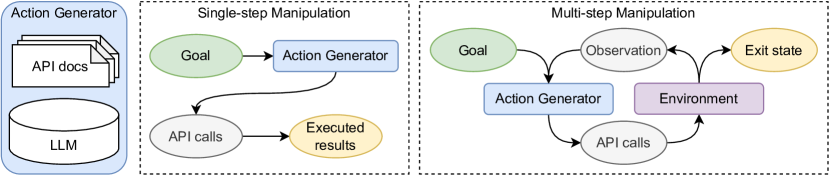
Figure 1: Overview of the paper's method and key components. From the original paper; copyright remains with the authors.
Core equations
Paper results
Up to 90% tool success, with performance competitive with GPT-4 on four of eight ToolBench tasks. No production online A/B is reported; there are no inferred online numbers.
Local reproduction
On planbench-mini with 120 episodes and seed 42, joint success is 1.0000 and average cost 0.8400.
auto-research agent-study --method toolbench --benchmark planbench-mini --episodes 120 --seed 42
auto-research evolve --model agent --dataset planbench-mini --direction "组合 toolbench 与已安装论文算子" --generations 2 --population 4
See the fixed metrics.
Reproduction boundaries
The local run checks the paper-specific objective, state update, or evaluation protocol. It does not reproduce the large model, multi-GPU training, private environments, or full public benchmark.