AutoGen: programmable multi-agent conversations
Represents agents as configurable conversational roles. Message routing and stopping conditions coordinate planners, executors, critics, humans, or tools.
Paper information
| Field | Details |
|---|---|
| Paper | AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation |
| Organization | Microsoft Research |
| First public release | 2023-08-16 |
| Authors' code | microsoft/autogen is public. |
| Adapter / method | autogen |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
Complex applications need models, tools, and humans to collaborate; hand-written control flow is hard to reuse. ConversableAgent and conversation programming let roles declare capabilities, reply policies, and termination conditions, then combine them through group chats or nested conversations.
flowchart LR
    U["User task"] --> P["Planner agent"]
    P --> E["Executor agent"]
    E --> C["Critic agent"]
    C -->|Revise| P
    C -->|Pass or terminate| O["Final result"]
    T["Tools or code executor"] <--> E
Key figure from the paper
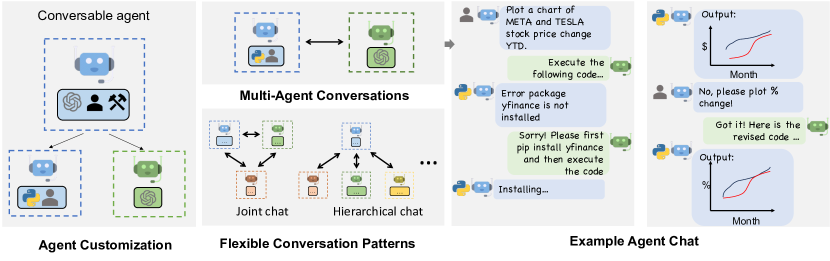
Figure 1: Core architecture, modules, and connections. From the original paper; copyright remains with the authors.
Core equations
AutoGen is an orchestration abstraction rather than a new loss. It can be written as a message-driven state machine:
Paper results
Mathematics, code generation, QA, and decision-making applications illustrate capability and development-efficiency gains over one agent. These are application evaluations and case studies, not a production online A/B test.
Local reproduction
On 120 fixed PlanBench mini episodes, joint success is 1.0000 and average cost 3.0000. Logs contain 120 plans, 360 cross-role messages, and 120 critic rounds.
See the stable metrics.
Reproduction boundaries
The planner/executor/critic message protocol, handoff, and explicit termination are implemented. The full AutoGen runtime, container code execution, and real LLM group conversations are not. A 1.0 score checks deterministic control flow, not the paper's application performance.