MemGPT: virtual memory for limited contexts
Implements core, working, and archival state. Working-context pressure triggers an interrupt and page-out, with page-in on later tasks.
Paper information
| Field | Details |
|---|---|
| Paper | MemGPT: Towards LLMs as Operating Systems |
| Organization | University of California, Berkeley |
| First public release | 2023-10-12 |
| Authors' code | The authors' public code, now Letta. |
| Adapter / method | memgpt |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
Limited context windows forget information in long documents and conversations. MemGPT borrows operating-system virtual memory: resident core information, active working context, and an external archive. Function calls move data, and interrupts or heartbeats control continued reasoning and interaction with the user.
flowchart LR
    U["User or document stream"] --> W["Working context"]
    C["Core memory"] <--> W
    W --> I{"Context pressure interrupt"}
    I --> A["Archival memory"]
    A --> P["Retrieve and page in"]
    P --> W
Key figure from the paper
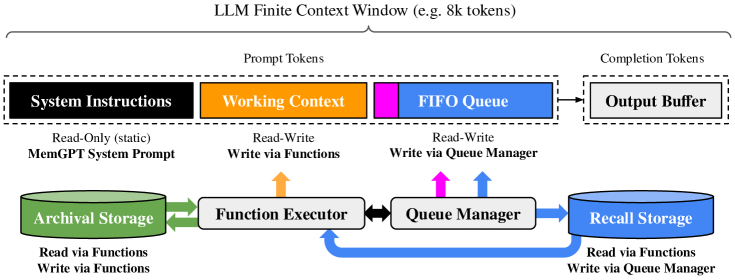
Figure 3: Overview of the paper's method and key components. From the original paper; copyright remains with the authors.
Core equations
Paper results
Document analysis beyond the base-model window and multi-session conversations compare fixed-context and retrieval baselines, showing persistent memory and dynamic reflection. No production online A/B is reported.
Local reproduction
EvoMem mini, 120 episodes, seed 42, memory size 24. Working memory uses half the capacity; pressure triggers page-out and repeated tasks page in from archival memory.
| Metric | Long-context baseline | MemGPT |
|---|---|---|
| Joint success | 1.0000 | 1.0000 |
| Average cost | 64.5000 | 0.9200 |
| Archival writes / page-ins / interrupts | 0 / 0 / 0 | 108 / 96 / 108 |
auto-research agent-eval --method memgpt --benchmark evomem-mini \
  --episodes 120 --memory-size 24 --seed 42
See the stable metrics.
Reproduction boundaries
Implements memory tiers, page-in/out, and interrupt counts. Archival retrieval uses deterministic keys, not embedding services or LLM function calling. Cost is the shared proxy cost, not tokens or online latency.