SWE-agent
An Agent–Computer Interface for browsing, editing, and testing code repositories with software-engineering agents.
Paper information
| Field | Details |
|---|---|
| Paper | SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering |
| Organization | Princeton University |
| First public release | 2024-05-06 |
| Authors' code | Public implementation |
| Adapter / method | swe-agent |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
A general-purpose shell exposes an overly broad action space and verbose output to an LLM. SWE-agent's specialized ACI constrains repository search, file viewing, precise editing, and testing so the model can locate the cause of an issue and validate a patch.
flowchart LR
    I["GitHub issue"] --> L["Find source and tests"]
    L --> E["Edit precisely"]
    E --> T["Run regression tests"]
    T -->|Fail| L
    T -->|Pass| P["Patch"]
Key figure from the paper
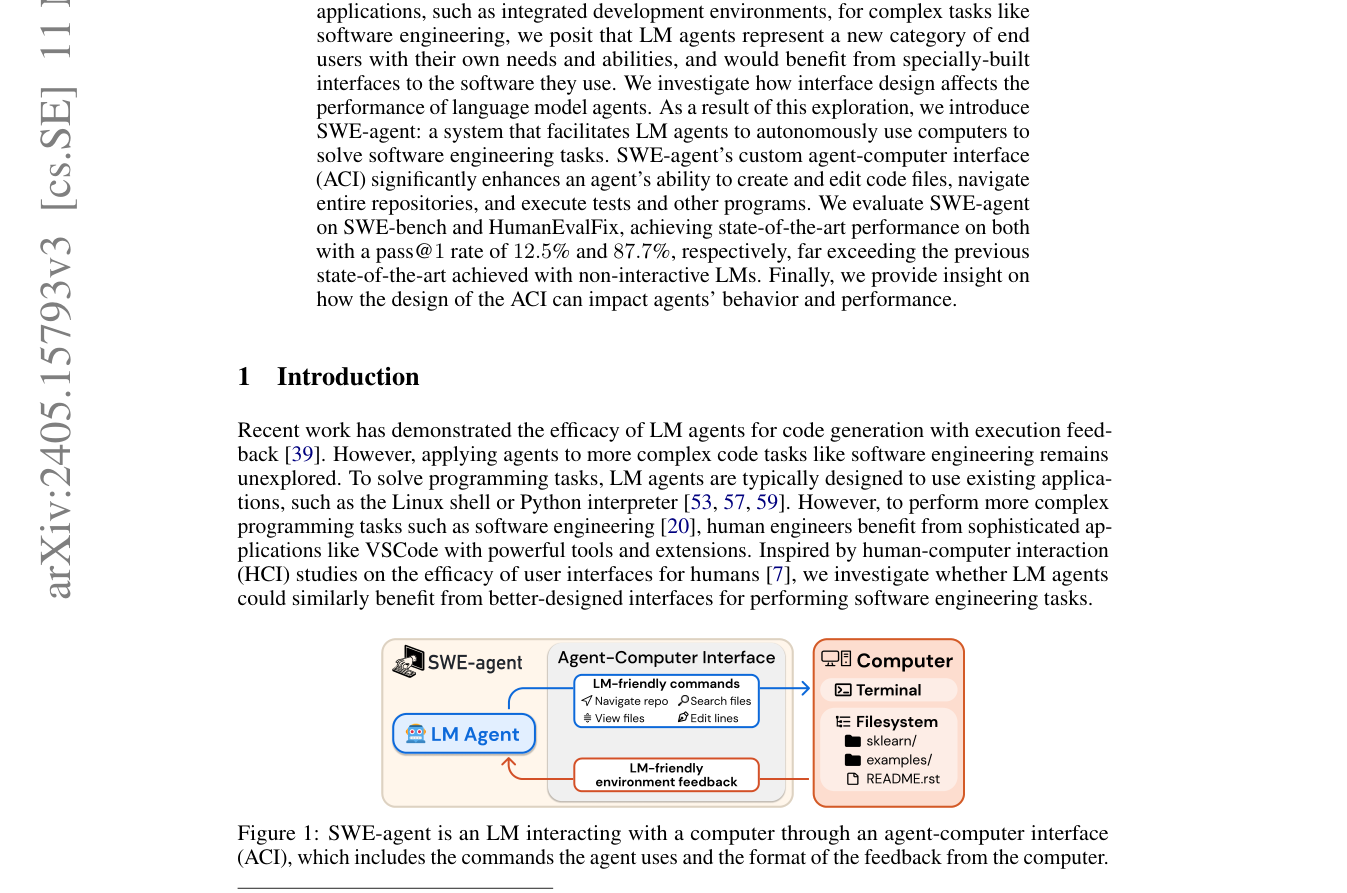
Figure 1: Overview of the paper's method and key components. From the original paper; copyright remains with the authors.
Core equations
Paper results
SWE-bench shows benefits from ACI when fixing real GitHub issues. It is an offline software-engineering benchmark, not a production online A/B test.
Local reproduction
The local ACI exposes only file reads, writes to solution.py, and a fixed unittest command. Each starting repository must fail a real test; the agent locates the issue, edits, and validates by exit code.
See the stable metrics.
Reproduction boundaries
This is an executable SWE-style microbenchmark, not official SWE-bench Lite data or its Docker images. The swebench-local name preserves that distinction. Local success is not the paper's resolved rate.