LOOP: PPO without a value network for long-horizon interactive agents
Fidelity: Checks multi-trajectory sampling, leave-one-out advantages, off-policy reuse, and per-token trust-region clipping. This is a deterministic mini-suite, not AppWorld 32B training.
Paper information
| Field | Details |
|---|---|
| Paper | Reinforcement Learning for Long-Horizon Interactive LLM Agents |
| Organization | Apple |
| First public release | 2025-02-03 |
| Authors' code | apple/ml-loop |
| Adapter / method | loop |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
Long-horizon digital-agent rollouts are expensive, and standard PPO also maintains a value model. LOOP combines PPO's trust region with a leave-one-out baseline so it can update repeatedly on a batch without a critic. Token-level importance-ratio clipping limits drifting tokens without discarding whole long trajectories.
flowchart LR
    E["Stateful AppWorld"] --> G["Multiple rollouts per task"]
    G --> B["Leave-one-out advantage"]
    B --> P["Per-token PPO clipping"]
    P --> U["Multiple epochs and off-policy reuse"]
    U --> E
Key figure from the paper
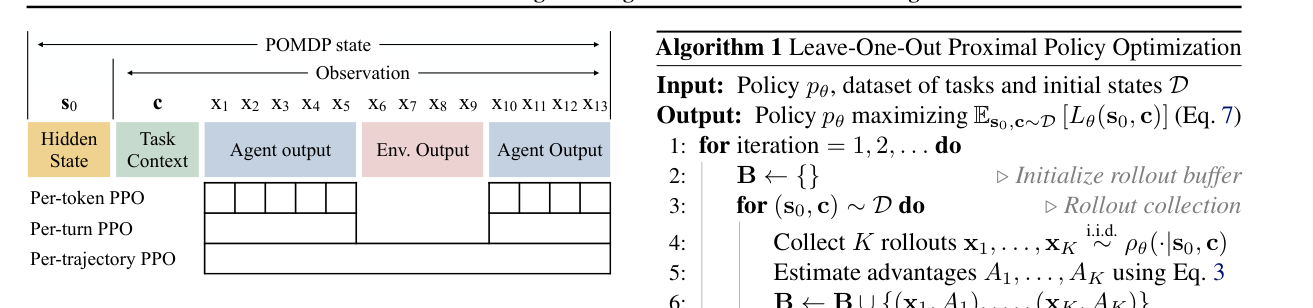
Figure 2: Compares per-token, per-turn, and per-trajectory PPO in an interactive POMDP. Copyright remains with the authors.
Core equations
Paper results
On AppWorld, the paper's 32B model beats the larger OpenAI o1 by 9 percentage points (15% relative). It also hallucinates less, consults API documentation more, and recovers from failures more often. No production online A/B is reported.
Local reproduction
| Metric | Local result |
|---|---|
| Joint success | 1.0000 |
| Average cost | 2.2000 |
| Off-policy reuse | 476 |
| Leave-one-out updates / per-token clips | 480 / 120 |
See the stable metrics.
Reproduction boundaries
Actual trajectory selection and statistical updates run locally, but not AppWorld, a 32B LLM, or gradient checkpoint training. A perfect mini-suite score checks trajectory control logic, not performance on the paper's tasks.