MUA-RL: bringing dynamic users into reinforcement learning for tool-using agents
Fidelity: Implements multi-turn simulated-user feedback, progressive intent clarification, actual tool observations, environment-token masks, and rewards based only on final completion. This is a deterministic tool mini-suite.
Paper information
| Field | Details |
|---|---|
| Paper | MUA-RL: Multi-turn User-interacting Agent Reinforcement Learning for agentic tool use |
| Organization | Meituan / Chinese Academy of Sciences / Peking University |
| First public release | 2025-08-26 |
| Authors' code | zzwkk/MUA-RL |
| Adapter / method | mua-rl |
| Local reproduction code | src/auto_research/agent_research/ |
Original paper
Motivation and method
Tool-use RL typically fixes the user request, but real users revise requirements in response to the agent. MUA-RL places an LLM-simulated user inside the rollout. The agent clarifies intent in conversation and calls real MCP or database tools. User messages and tool results do not contribute to policy loss; exploration uses only the final task-completion reward.
flowchart LR
    U["Simulated user"] --> A["Agent clarification"]
    A --> T["Real MCP / database tools"]
    T --> O["Environment observation"]
    O --> U
    O --> R["Final task-completion reward"]
    R --> A
Key figure from the paper
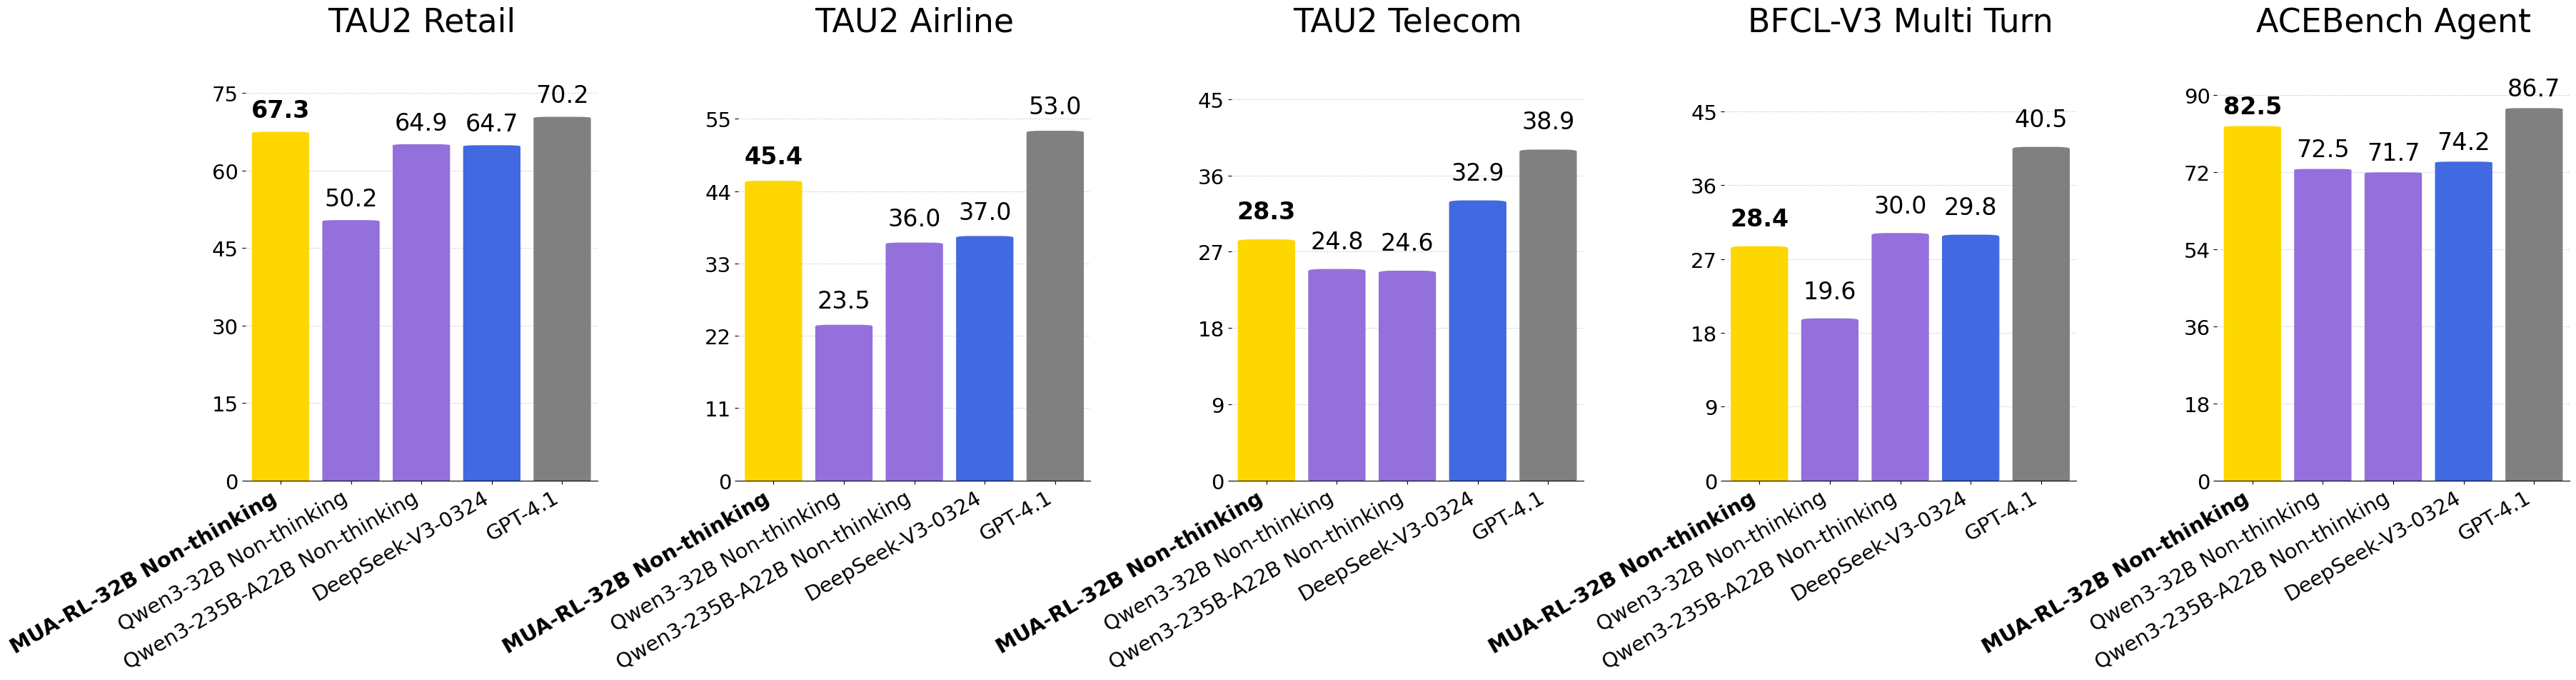
Figure 1: Overall MUA-RL results on several multi-turn tool benchmarks. Copyright remains with the authors.
Core equation
User messages and tool responses are environment tokens and excluded from policy-token loss.
Paper results
MUA-RL-32B scores 67.3/45.4/28.3 on TAU2 Retail/Airline/Telecom, 28.4 on BFCL-V3 Multi Turn, and 82.5 on ACEBench Agent. No production online A/B is reported.
Local reproduction
| Metric | Local result |
|---|---|
| Joint success | 1.0000 |
| Average cost | 2.2500 |
| Simulated-user turns / intent refinements | 360 / 240 |
| Tool responses / final rewards | 360 / 120 |
See the stable metrics.
Reproduction boundaries
Local simulated users reveal constraints deterministically from task context; tools return actual mini-suite states. There is no external LLM user or production database. This tests interaction and reward boundaries, not original model scale.