SPO++: aligning event time and token measure in asynchronous agent RL
Core-mechanism mini-suite. Freezes prompt value at each dispatch and consumes advantages under an action-token measure.
Paper information
| Field | Details |
|---|---|
| Paper | arXiv 2608.24870 |
| Organization | Renmin University of China, the first listed affiliation of the first author |
| First public release | 2026-08-25 (arXiv v1) |
| Authors' code | No public author code was found on 2026-08-26. |
| Adapter / method | spo-plus-plus |
| Local reproduction code | src/auto_research/agent_research/latest_20260826.py |
Original paper
Motivation and method
SPO avoids waiting for sibling rollouts with a single rollout and persistent prompt value. Completion order can contaminate history, and trajectory whitening uses a different measure than token-mean actor loss. SPO++ organizes evidence by policy-generation event, freezes the baseline at dispatch, and normalizes advantages with action-token-count weights.
flowchart LR
  D[dispatch at policy event z] --> F[freeze prompt value]
  F --> R[async rollout]
  R --> E[event-time evidence update]
  R --> N[action-token measure normalization]
  N --> U[token-mean actor update]
Key figure from the paper
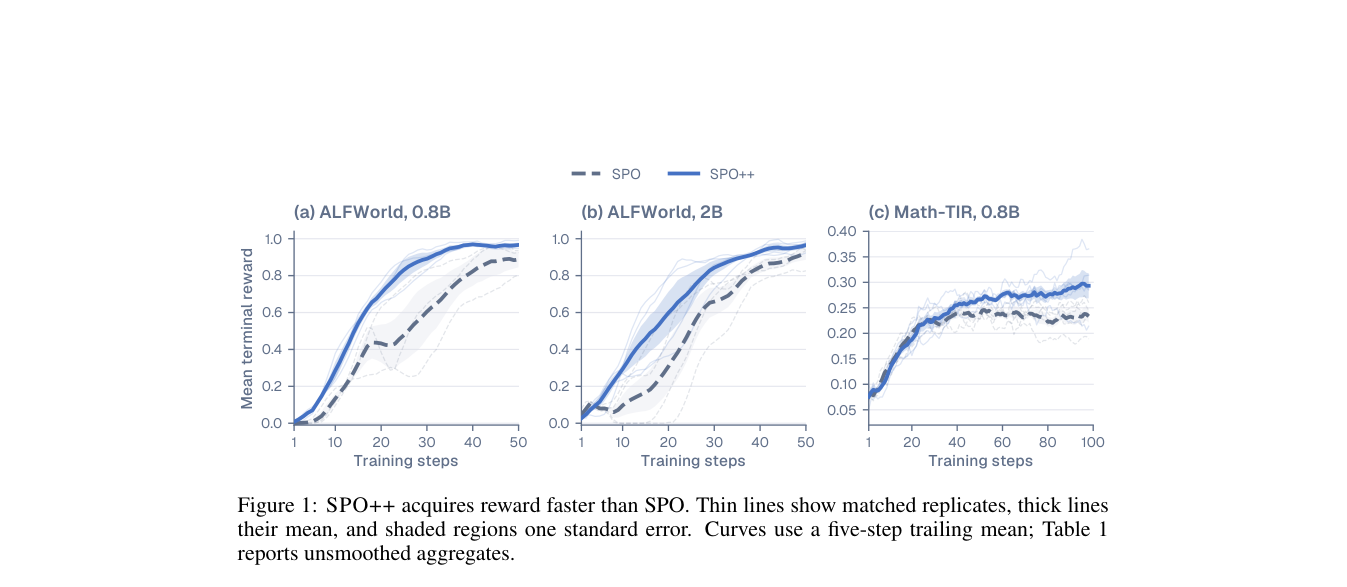
Figure 1: Overview of the paper's method and key components. From the original paper; copyright remains with the authors.
Core equations
Paper results
Relative to SPO, ALFWorld reward-curve area rises +19.00 / +15.92 points for 0.8B/2B, and Math-TIR +2.50 points. No industrial online A/B is reported.
Local reproduction
On 120 PlanBench-mini episodes, joint success is 1.0000 and average cost 0.6400. The run executes 120 value freezes and 360 action-token measure updates. See the metrics and batch index.
Reproduction boundaries
The deterministic mini-suite checks event-time state and measure alignment. No asynchronous Qwen3.5, ALFWorld, or Math-TIR training was run.