Data Scarcity and Model Sparsity: Mixtures-of-Experts Overfit More to Repeated Data
L1 regularization schedule diagnostic, no large-scale pretraining.
Paper information
| Field | Details |
|---|---|
| Paper | Data Scarcity and Model Sparsity: Mixtures-of-Experts Overfit More to Repeated Data |
| Institution | Stanford University (first author). |
| First public release | 2026-09-10 |
| Author code | No public author repository found as of 2026-09-14. |
| Local adapter or method key | repeat-aware-moe |
| Local reproduction code | src/auto_research/foundation_latest_20260914.py |
Paper method and evidence
MoE can overfit repeated data sooner than dense models. Stronger masking and dropout suppress expert memorization; adjust regularization according to repetition and sparsity.
flowchart LR
  D[Data repetition and sparsity] --> R[Choose masking and dropout]
  R --> S[Regularize expert learning]
Original paper figure
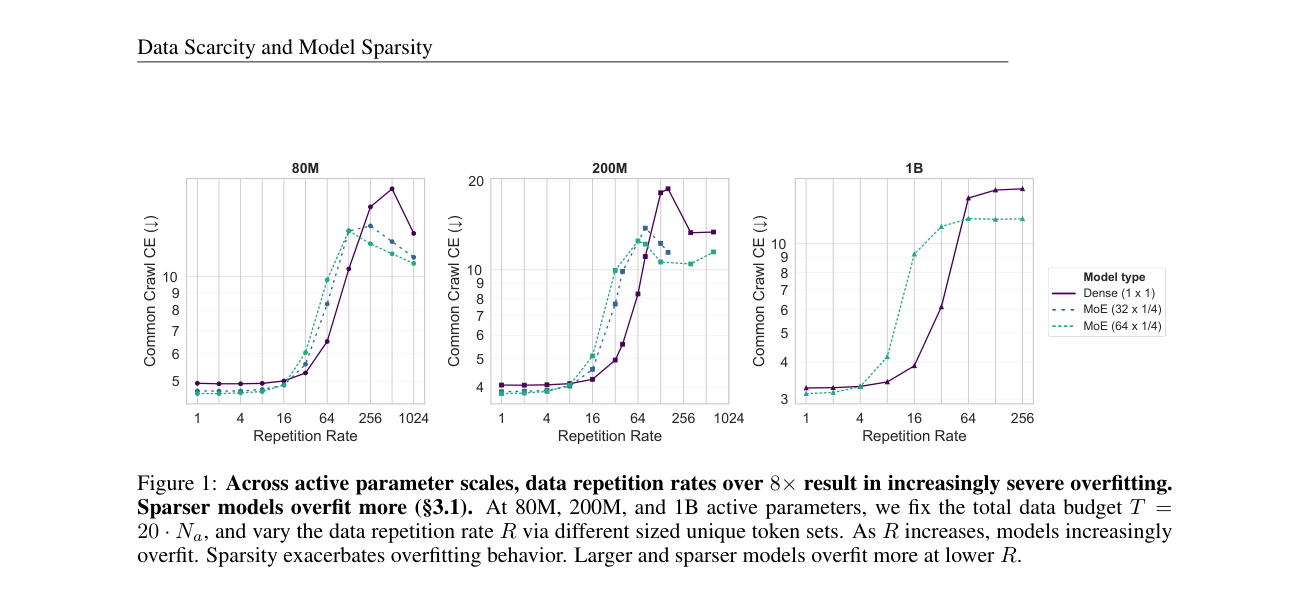
The original figure shows the repetition/sparsity study. From the original paper; copyright remains with the authors.
Reported results
With strong regularization, the paper reports that MoE can still beat dense models at 64-fold data repetition. This is not an online or local result.
Local reproduction
Three-seed metrics use the same public fixtures, budget, and seeds. The deterministic reference exposes decisions and state transitions; tests verify invariants and boundaries. These are not capability or production results.