MoEZip: Routing-Aware KV Cache Compression for Sparse Mixture-of-Experts LLMs
L1 KV selection and gather; diagnostic only. No full MoE model or compressor baseline.
Paper information
| Field | Details |
|---|---|
| Paper | MoEZip: Routing-Aware KV Cache Compression for Sparse Mixture-of-Experts LLMs |
| Affiliations | Minsang Kim: Korea University and SK Telecom; Seung Jun Baek: Korea University. |
| First public release | 2026-10-21 13:06:30 UTC |
| Author code | kmswin1/MoEZip at 197959dbae2adfab7ec233f584ce951b827e04cc contains only README and Apache-2.0 LICENSE, no implementation. README examples are not executable release evidence. |
| Local key | moezip; no adapter |
| Local code | src/auto_research/foundation_models/moezip.py |
| Local evidence | Local mechanism metrics; A100 validation receipt |
What the paper changes
Removing KV can change attention and routing. Use Fisher trace from prefill instruction-token gates as a sensitivity proxy and propagate it to context locations with headwise maximum attention. Retain global routing anchors in all layer/heads and fill remaining budget using external base-compressor scores, without future answer tokens.
Original paper figure
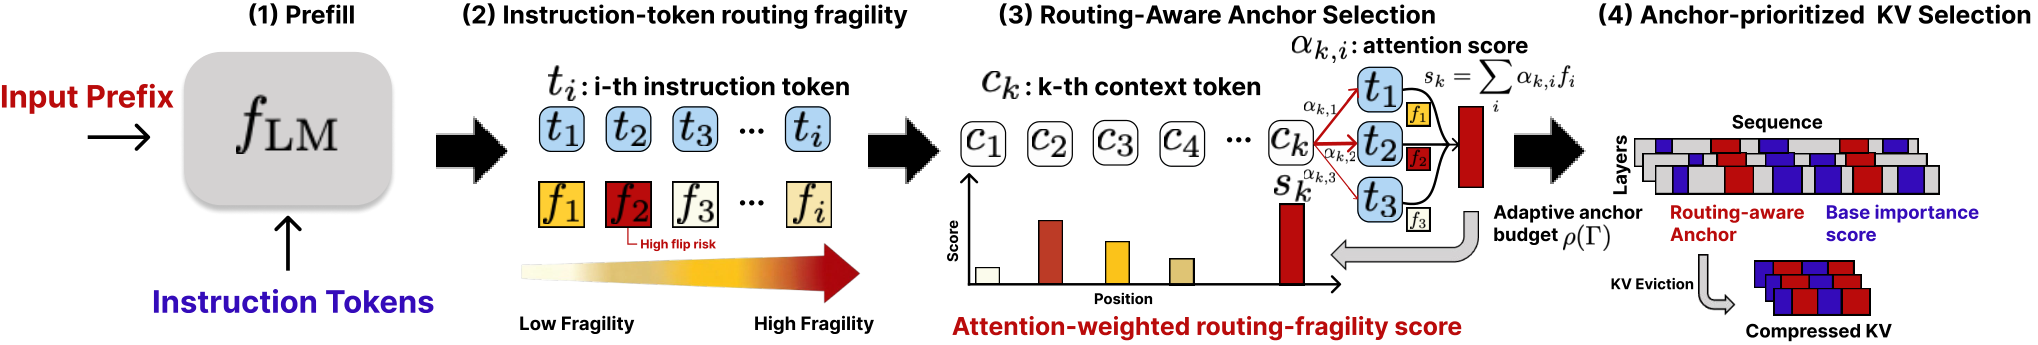
Original figure from the reviewed paper, reused without redrawing. See figure provenance.
Core equations
Threshold is 85% of the theoretical maximum trace; set \(\rho=.05+.20\Gamma\) and clip floor budget to 32–128, also capped at the actual budget locally. Gather deduplicated anchors and remaining base picks in original index order, preserving position IDs. Trace is a direction-averaged curvature proxy, not router Jacobian or a guarantee of top-k flip; gold-answer flip analysis is offline only. Softmax and sigmoid trace expressions coincide on a vector summing to one, so compare the two gate transforms on the same logits.
Results reported by the authors
Table 1 Qwen3-30B at 10% retention: KVZip 19.51, reconstruction-query/cache-reusable MoEZip-Recon 41.95 and query-conditioned MoEZip 44.89. Conditioning and reuse differ. No local model/LongBench or production A/B.
Local reproduction and limits
fisher_trace, select_cache and compress_cache implement both gates, max aggregation, budget, duplicate exclusion and real gather; no KVZip reimplementation. Synthetic fixture: two layers, three heads, eight instruction tokens/experts, 512 context, 256 rows/head. Explicit Fisher matrix, uniform/peaked 32–64 anchors, max-vs-mean, retention across heads, tiny/zero budgets, indices and invalid input checks. Three seeds are L1 only.
PYTHONPATH=src python scripts/run_oct23_priority_components.py \
  --device cpu --seeds 42,43,44 --source-commit COMMIT \
  --frozen-proof oct23-frozen-proof.json --output runs/oct23-cpu-new.json
Full experiment: not reproduced
Appendix C reports all A100-80GB, typically two GPUs/run and eight for 235B, roughly 15,000–16,000 A100 GPU-hours excluding exploration/failures. No checkpoints, benchmark probe, automated training or Evolve.