简体中文 · English
Constitutional AI: Learning harmlessness from AI feedback
Implements the two stages of self-critique and revision followed by SFT on revised examples and RLAIF with AI preferences. The local candidate policy is not Anthropic's large-model safety training.
Paper information
| Field | Details |
|---|---|
| Paper | Constitutional AI: Harmlessness from AI Feedback |
| Institution | Anthropic |
| First public release | 2022-12-15 |
| Author code | Supplementary materials released; not a complete training framework. |
| Local adapter or method key | constitutional-ai |
| Local reproduction code | src/auto_research/post_training/ |
Original paper summary
Background and main changes
Labeling individual harmful responses is costly and makes underlying values opaque. The paper distills human supervision into natural-language principles. In stage one, the model critiques and rewrites its responses according to the principles, then learns by SFT on the revisions. In stage two, AI compares responses, a preference model is trained, and its reward drives RLAIF.
flowchart LR
    X["Initial answer"] --> C["Self-critique using the constitution"]
    C --> V["Generate revised response"]
    V --> S["SL: fine-tune on revisions"]
    S --> P["Sample response pairs"]
    P --> A["AI preferences based on principles"]
    A --> R["Preference model + RL (RLAIF)"]
Key figure from the paper
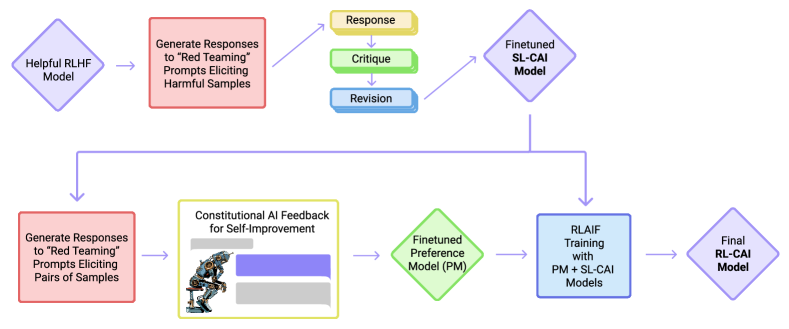
Figure 1: Overall design and components. From the paper; copyright belongs to the authors. Click for the source.
Core equations
The first term is SFT on revised responses. In the second, chosen and rejected labels come from AI preferences generated using the constitution.
Offline and online results
Human evaluations show that RLAIF reduces harmfulness while retaining helpfulness and gives fewer evasive refusals than the SL-only model. Chain-of-thought principle judgments further improve transparency. No production online A/B test is reported.
Local reproduction
Public GSM8K candidate data (512/128), 300 steps, seed 42. Four auditable principle dimensions guide critique/revision and AI preferences. Human preference labels are not read.
| Metric | Untrained policy | Constitutional AI |
|---|---|---|
| Accuracy | 0.1641 | 0.8438 |
| Mean reward | 0.3126 | 0.8617 |
| KL(reference) | 0.0000 | 1.0214 |
auto-research post-train --algorithm constitutional-ai \
  --dataset gsm8k-candidate --maximum-examples 512 \
  --steps 300 --seed 42 --offline
Stable metrics: p0-missing-post-training-gsm8k-seed42.json.
Scope
Implements explicit principle scoring, SFT on self-revisions, and updates from AI preference ranking. The GSM8K dimensions are correctness, format, process, and brevity, not safety red-team data. The run does not train a standalone preference model or run large-model PPO.