SteerLM: supervised fine-tuning conditioned on multiple attributes
Implements explicit attribute annotation, target-conditioned selection, and SFT. Four local attributes do not reproduce NVIDIA's 43B model.
Paper information
| Field | Details |
|---|---|
| Paper | SteerLM |
| Organization | NVIDIA |
| First public release | 2023-10-09 |
| Authors' code | NVIDIA NeMo-Aligner |
| Adapter / method | steerlm |
| Local reproduction code | src/auto_research/post_training/ |
Original paper
Motivation and method
Traditional RLHF reduces multidimensional preferences to one reward, and users cannot change the target at inference. SteerLM uses an attribute predictor to label responses for helpfulness, quality, and other properties, adds attributes and values as conditions in ordinary SFT, and lets the user specify target attributes at inference.
flowchart LR
    P["Prompt and response"] --> A["Predict and annotate attributes"]
    A --> D["Prompt and attribute values"]
    D --> S["Attribute-conditioned SFT"]
    T["Target attributes at inference"] --> G["Controllable generation"]
    S --> G
Key figure from the paper
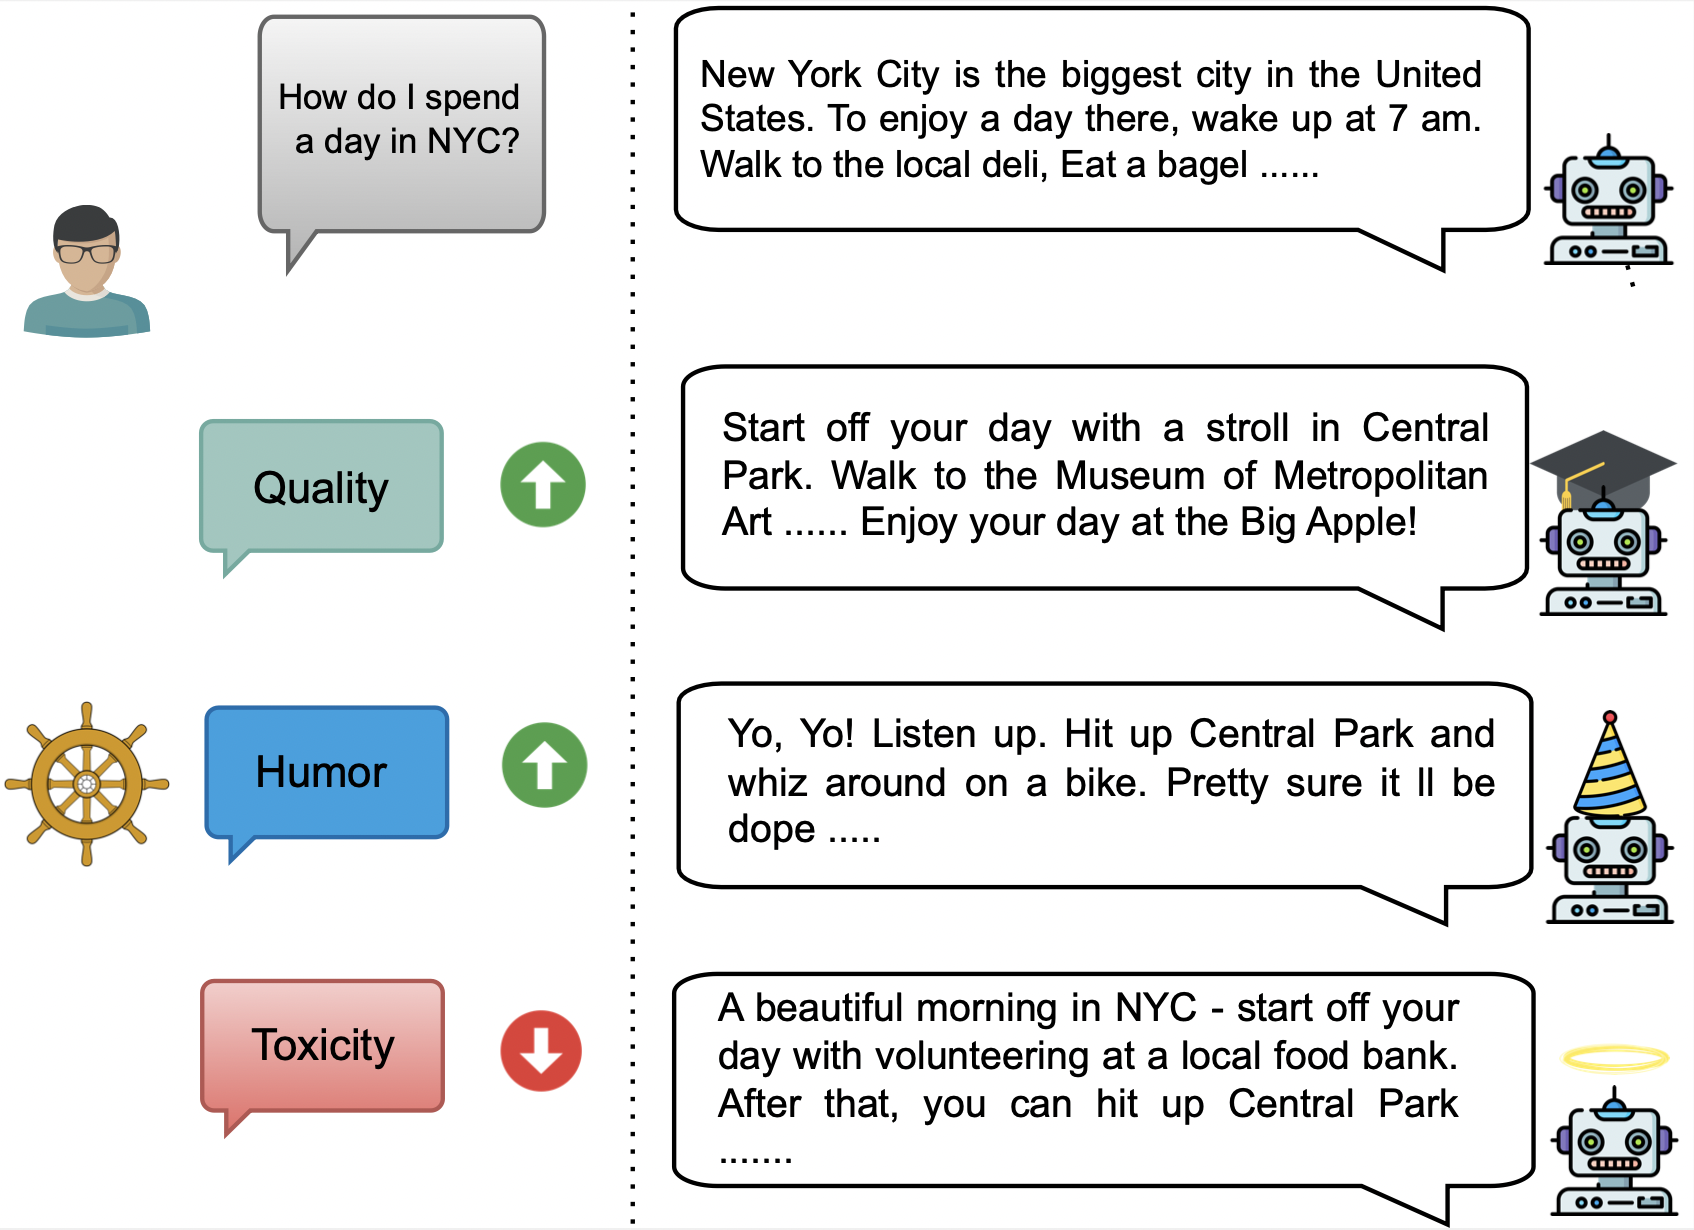
Figure 1: Overview of the paper's method and key components. From the original paper; copyright remains with the authors.
Core equation
Paper results
On 80 Vicuna prompts scored by GPT-4, SteerLM 43B achieves 104.2% of ChatGPT-3.5's score. Human Elo is 1040, above ChatGPT-3.5 at 981 and Guanaco-65B at 977. No production online A/B is reported.
Local reproduction
Four reward axes supply auditable attribute labels. The target-attribute vector selects responses before conditional SFT.
| Metric | Untrained policy | SteerLM |
|---|---|---|
| Accuracy | 0.1641 | 0.8516 |
| Mean reward | 0.3126 | 0.8654 |
| KL(reference) | 0.0000 | 0.9112 |
auto-research post-train --algorithm steerlm --dataset gsm8k-candidate \
  --maximum-examples 512 --steps 300 --seed 42 --offline
See the stable metrics.
Reproduction boundaries
Multidimensional annotation and conditional SFT are retained. Local attributes are deterministic reward axes from public candidate data. No large attribute predictor or genuine text-token conditional generation was implemented.