GPPO: PPO clipping that preserves out-of-range gradients
Isolates the RL update on a public candidate policy or deterministic agent mini-suite. The lightweight experiment does not establish paper-scale model or benchmark results.
Paper information
| Field | Details |
|---|---|
| Paper | GPPO: PPO clipping that preserves out-of-range gradients (arXiv 2508.07629) |
| Organization | Alibaba Group / Klear-Reasoner Team |
| First public release | 2025-08-11 |
| Authors' code | No standalone public implementation of the algorithm was found. |
| Adapter / method | gppo |
| Local reproduction code | src/auto_research/post_training/ |
Original paper
Motivation and method
Ordinary PPO zeroes gradients for positive advantages with high ratios and negative advantages with low ratios outside the clip range. This can suppress exploration and learning from negative samples. GPPO keeps PPO's forward clipped objective while restoring backward signals in those regions with a stop-gradient boundary weight.
flowchart LR
    R["importance ratio"] --> P["PPO clipped surrogate"]
    P --> F["same forward objective"]
    R --> G["stop-gradient boundary weight"]
    G --> B["preserved backward gradient"]
Key figure from the paper
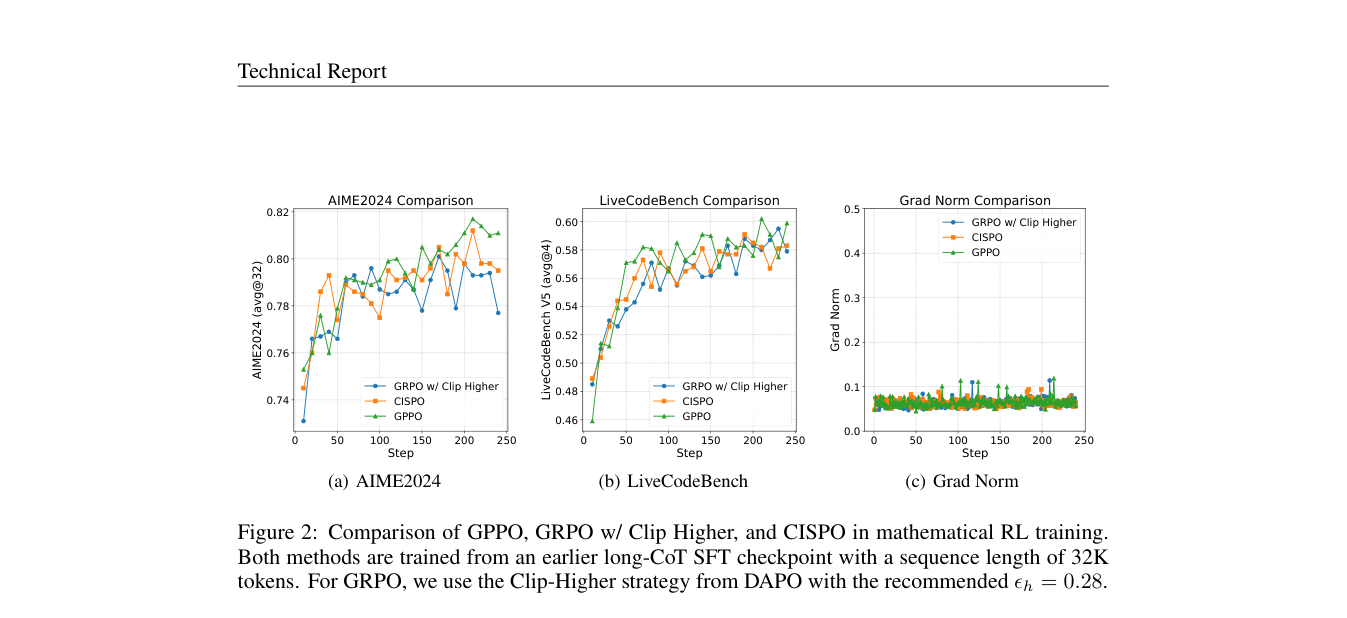
Figure 2: Training flow and key optimization steps. From the original paper; copyright remains with the authors.
Core equations
Paper results
Klear-Reasoner reports improved exploration and use of negative samples with GPPO, and strong whole-model results on AIME 2024/2025 and LiveCodeBench. No online A/B is reported.
Local reproduction
On the GSM8K candidate policy, distinguish ordinary and out-of-range PPO samples. The forward pass still computes the clipped surrogate; the backward pass preserves out-of-range gradients with clip-boundary weights.
auto-research post-train --algorithm gppo --dataset gsm8k-candidate --maximum-examples 256 --steps 120 --seed 42
See the fixed-seed aggregate metrics.
Reproduction boundaries
No Klear-Reasoner or long-chain-of-thought SFT is trained locally. Only the GPPO forward/backward separation is reproduced.