KPop: Adaptive train–inference mismatch masking with binary KL
Isolated candidate-policy RL mechanism, not paper-scale async training.
Paper information
| Field | Details |
|---|---|
| Paper | KPop (arXiv 2606.15079) |
| Institution | Ling / Ring Team. |
| First public release | 2026-06-13 |
| Author code | No standalone algorithm repository found. |
| Local adapter or method key | kpop |
| Local reproduction code | src/auto_research/post_training/ |
Paper method and evidence
Asynchronous rollout and training probabilities can disagree. A fixed ratio mask can reject legitimate exploration or keep harmful gradients. Collapse the sampled token and remaining vocabulary to a Bernoulli distribution; retain its update only if forward and reverse binary KL meet the threshold.
flowchart LR
  P[Training and rollout probabilities] --> B[Collapse to Bernoulli pair]
  B --> K[Check both KL directions]
  K --> M[Gate sampled-action gradient]
Original paper figure
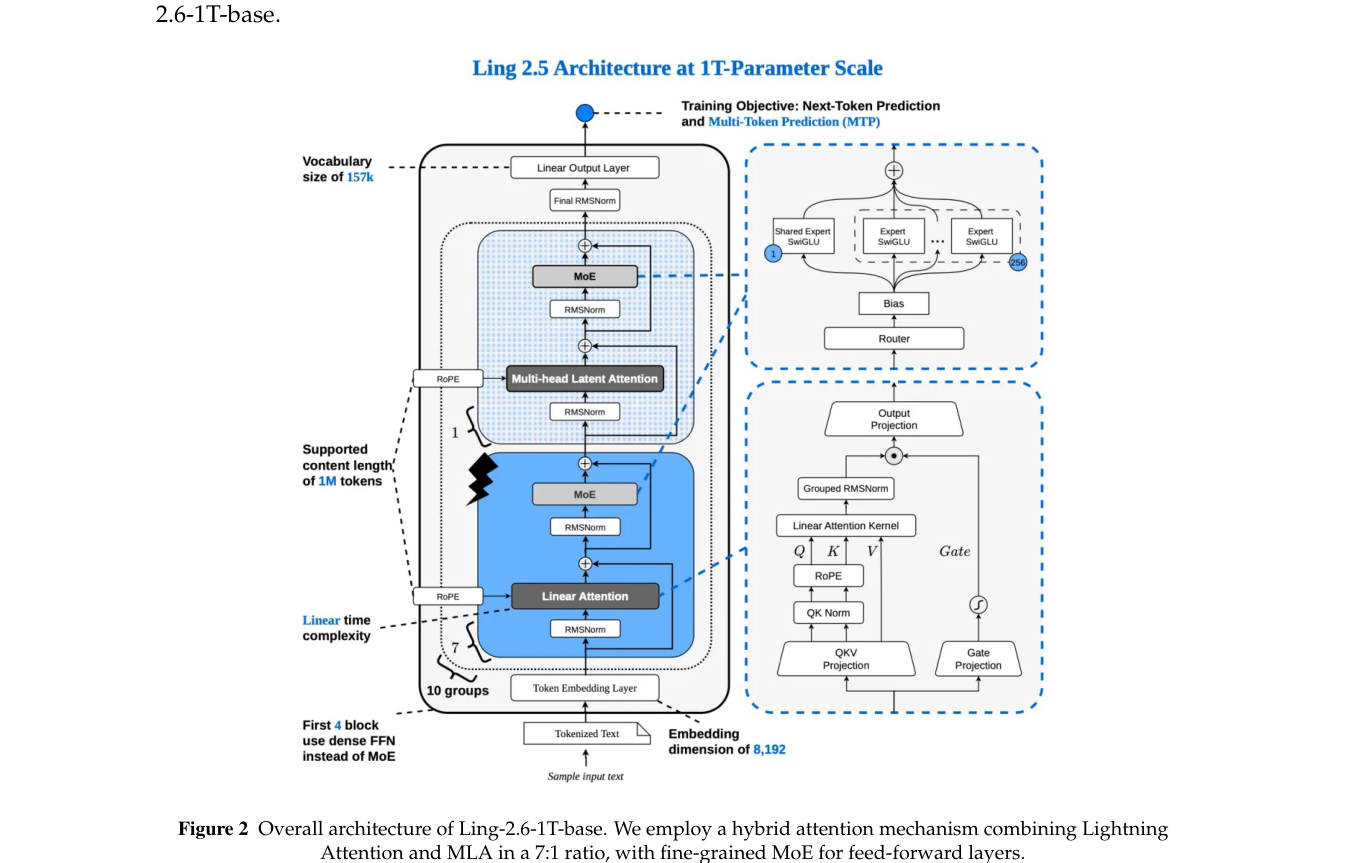
The original figure describes the training mechanism. From the original paper; copyright remains with the authors.
Core equation
Reported results
The Ling/Ring 2.6 report uses KPop in large-scale asynchronous agentic RL for coding, search, tools and workflows. No production A/B was reported.
Local reproduction
Compute bidirectional binary KL from rollout/training candidate distributions and use the mask to control actual policy gradients.
auto-research post-train --algorithm kpop --dataset gsm8k-candidate --maximum-examples 256 --steps 120 --seed 42
Fixed-seed summary. No real serving/training engine, MoE routing or trillion-parameter cluster.