ReCo
Objective-level candidate-policy mechanism, not full-parameter RLVR.
Paper information
| Field | Details |
|---|---|
| Paper | arXiv 2607.26862 |
| Institution | Seoul National University. |
| First public release | 2026-07-29 (arXiv v1) |
| Author code | No public author implementation found. |
| Local adapter or method key | reco-grpo |
| Local reproduction code | src/auto_research/post_training/algorithms.py |
Paper method and evidence
GRPO can resample high-probability responses and amplify saturated tokens, reducing reasoning diversity at large k. Weight responses inversely by expected occurrence in the rollout group, then use a Bernoulli variance ratio to focus updates on unsaturated decisions.
flowchart LR
  O[Rollout responses] --> W[Downweight expected repetitions]
  T[Token probabilities] --> V[Variance ratio]
  W --> U[Policy gradient]
  V --> U
Original paper figure
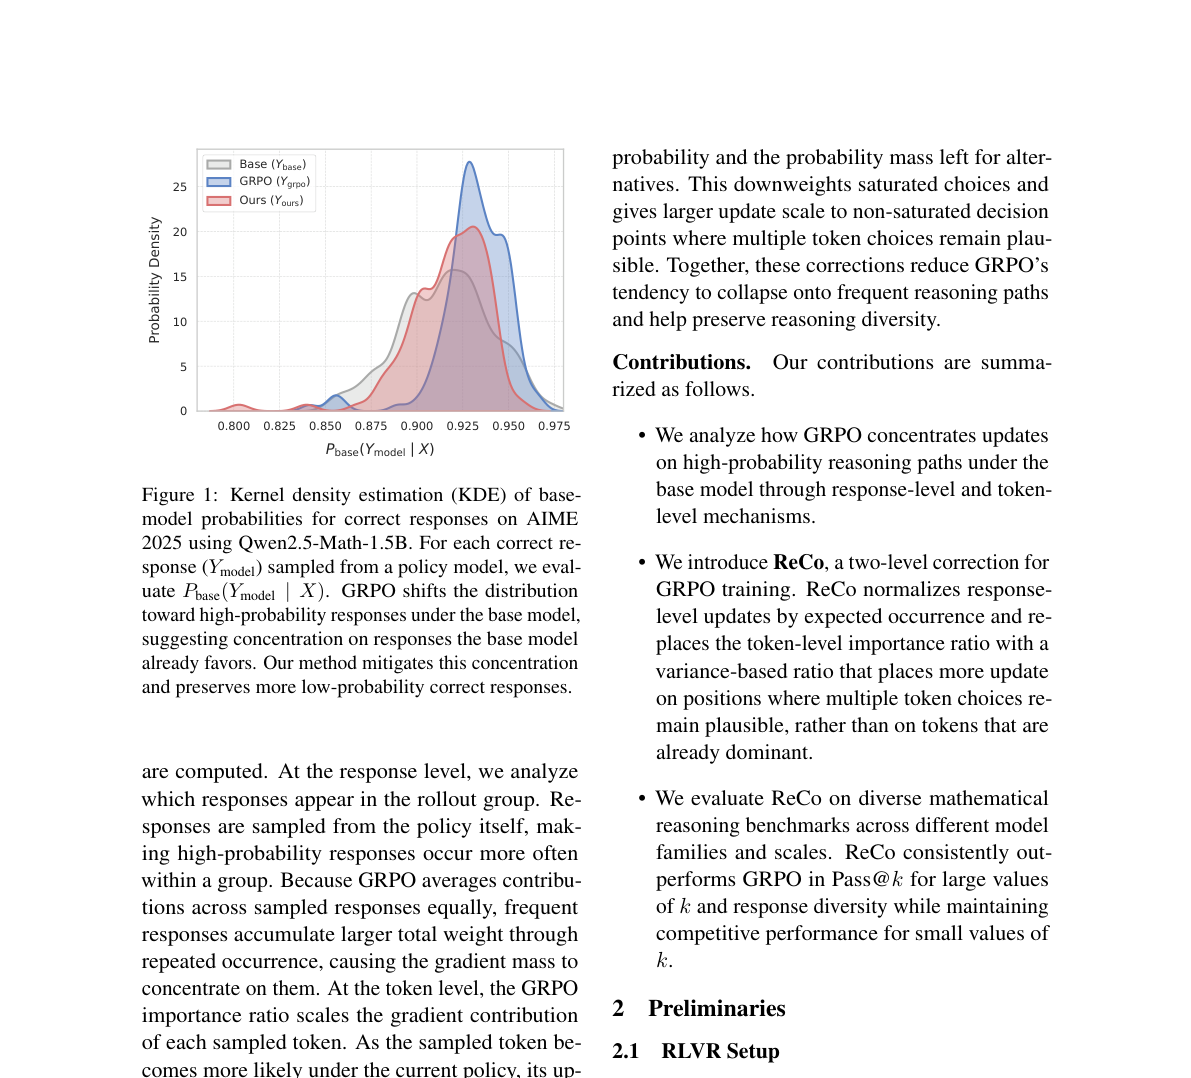
The original figure illustrates response- and token-level reweighting. From the original paper; copyright remains with the authors.
Core equation
Reported results
Five-math-benchmark mean Pass@64: Qwen2.5-Math-1.5B GRPO 65.8, ReCo 68.9; 7B 69.0→72.6; Llama-3.1-8B-Instruct 46.2→57.5. No production A/B.
Local reproduction
Apply expected-occurrence weighting, variance ratio, PPO clipping, KL and policy refresh every 16 steps.
auto-research post-train --algorithm reco-grpo --dataset gsm8k-candidate \
  --steps 120 --group-size 4 --maximum-examples 256 --seed 42
GSM8K candidate accuracy 0.1719→0.8750, mean reward 0.3124→0.8798; final mean variance ratio 0.9842, seven refreshes. Full metrics. Candidate actions replace full responses; no comparable Pass@64 or natural-language Self-BLEU.