Unlocking the Critic: Reward-Free Policy Optimization for LLM Post-Training
L1 mechanism diagnostic. Frozen-critic debiasing, binary rewards, and GAE; no long-chain model training.
Paper information
| Field | Value |
|---|---|
| Paper | Unlocking the Critic: Reward-Free Policy Optimization for LLM Post-Training |
| Affiliations | University of Luxembourg, first author's affiliation |
| First public release | 2026-09-29 (arXiv v1) |
| Authors' code | No public author repository found as of 2026-09-30. |
| Adapter / method | rfpo |
| Local code | src/auto_research/post_training/latest_20260930_closure.py |
Original paper
Background and contribution
Freeze a calibrated critic and reuse prefix success probability as rollout reward, GAE baseline, and unfinished-trajectory forecast. Remove length bias before binarization to limit exploitation of critic bias.
flowchart LR
  I[Prefix] --> C[Frozen critic] --> D[Length debiasing and binary reward] --> G[GAE and forecast]
Key figure from the paper
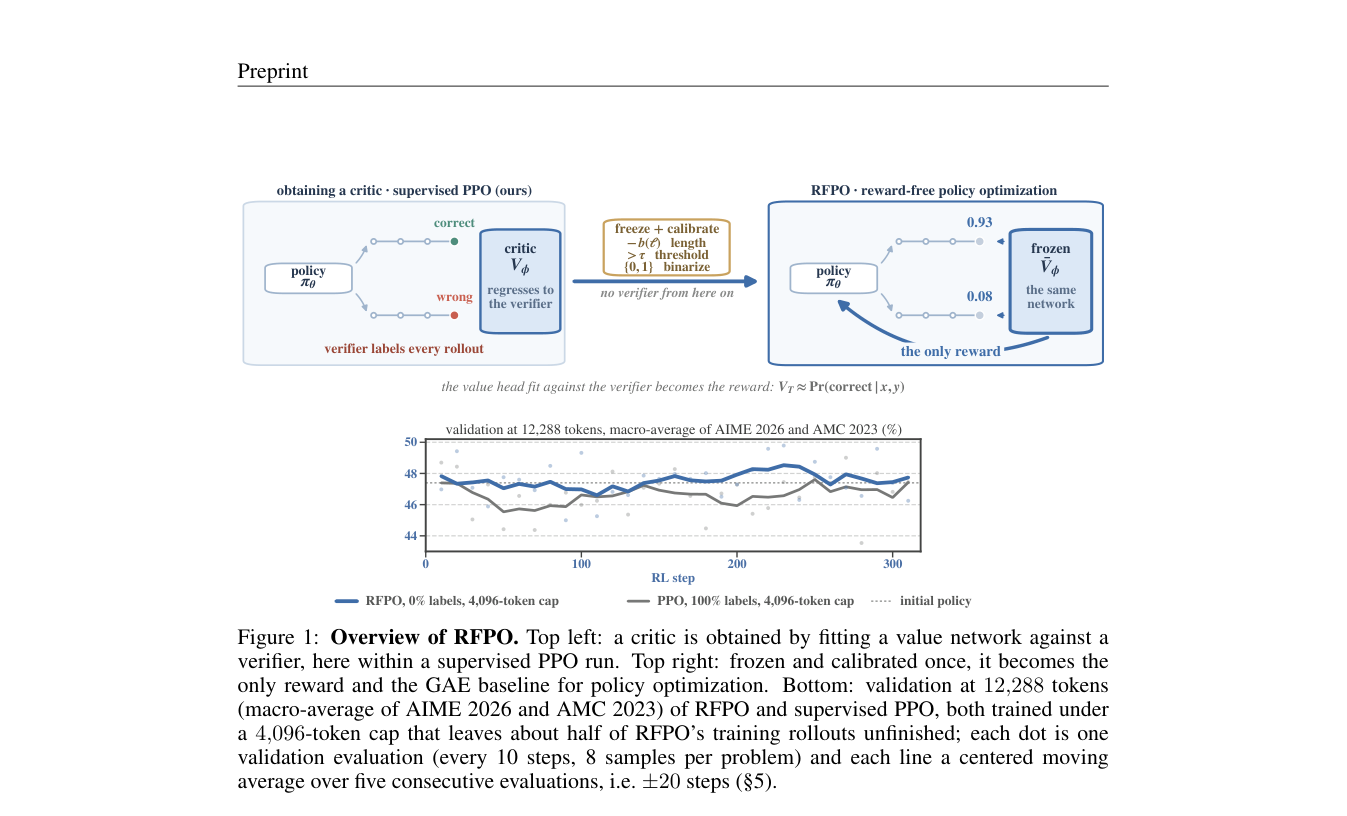
Original Figure 1: critic-based training. From the paper; copyright belongs to the authors. Not a local result.
Core mechanism
The reference preserves gates, masks, recursion, credit, and acceptance behavior. Tests check gradient isolation, type boundaries, and determinism.
Paper results
Benchmarks, speed, and learning curves belong to the paper, not the three-seed mini-suite or online impact.
Local reproduction
Three-seed diagnostics are diagnostic_only=true, excluded from capability rankings.
Reproduction limits
The critic mechanism runs but does not train a long-chain reasoning model.