Byte Latent Transformer: Patches Scale Better Than Tokens
Core patch mechanism on public data, not the 8B model.
Paper information
| Field | Details |
|---|---|
| Paper | arXiv 2412.09871 |
| Institution | Meta FAIR. |
| First public release | 2024-12-13 (arXiv v1) |
| Author code | facebookresearch/blt. |
| Local adapter or method key | blt |
| Local reproduction code | src/auto_research/reproductions/blt/ |
Paper method and evidence
Process bytes directly, segmenting dynamic patches by next-byte entropy. The global Transformer operates on patches, while local encoders and decoders recover bytes.
flowchart LR
  X[Byte sequence] --> H[Estimate next-byte entropy]
  H --> P[Dynamic patches]
  P --> T[Global Transformer]
  T --> D[Local byte recovery]
Original paper figure
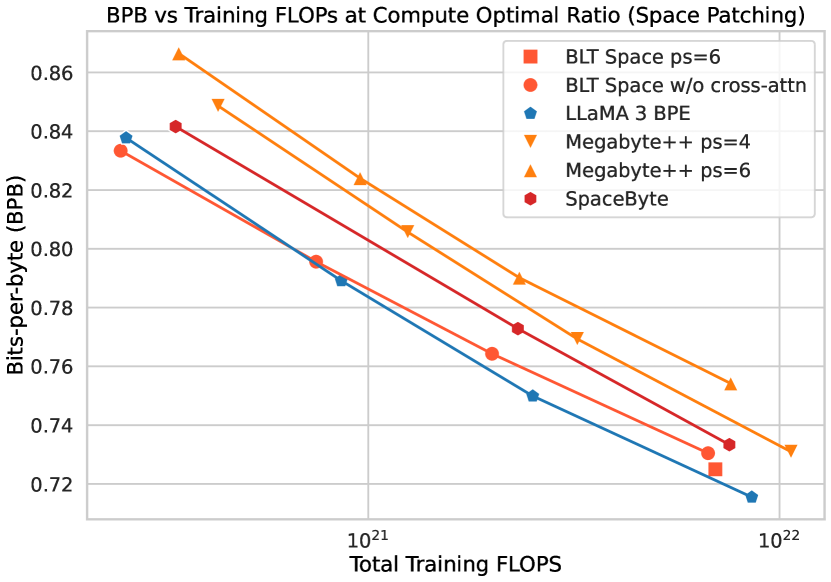
The original figure shows entropy-based patching. From the original paper; copyright remains with the authors.
Core equation
Reported results
The authors report better scaling at fixed FLOPs and stronger robustness to noise and language variation.
Local reproduction
WikiText-2, 12 steps, 64d/two layers, seed 42, matched llama_modern: PPL 421.18→412.21 (-2.13%) with the same parameters, tokens, optimizer and steps. Learn surprisal boundaries, share latents across nearby low-entropy positions and expand back to targets. A 512-symbol tokenizer only approximates bytes; no full local encoders/decoders or original-scale claim.