AgenticRecTune: Optimize recommendation with multiple agents and a self-evolving SkillHub
Three real local rounds of proposals, evaluation and SkillHub inheritance.
Paper information
| Field | Details |
|---|---|
| Paper | Paper or original source |
| Institution | Google / Discover. |
| First public release | 2026-04-21 (arXiv v1) |
| Author code | No official author code linked by the paper as checked on 2026-08-09. |
| Local adapter or method key | agentic-rec-tune |
| Local reproduction code | src/auto_research/reproductions/agentic_rec_tune/ |
Paper method and evidence
Actor proposes, Critic checks risk, Insight summarizes findings, Skill persists knowledge, and Online returns experiment-platform feedback across retrieval, fusion and reranking.
flowchart LR
  A[Actor proposes ranking weights] --> B[Critic evaluates validation]
  B[Critic evaluates validation] --> C[Summarize and inherit SkillHub]
Original paper figure
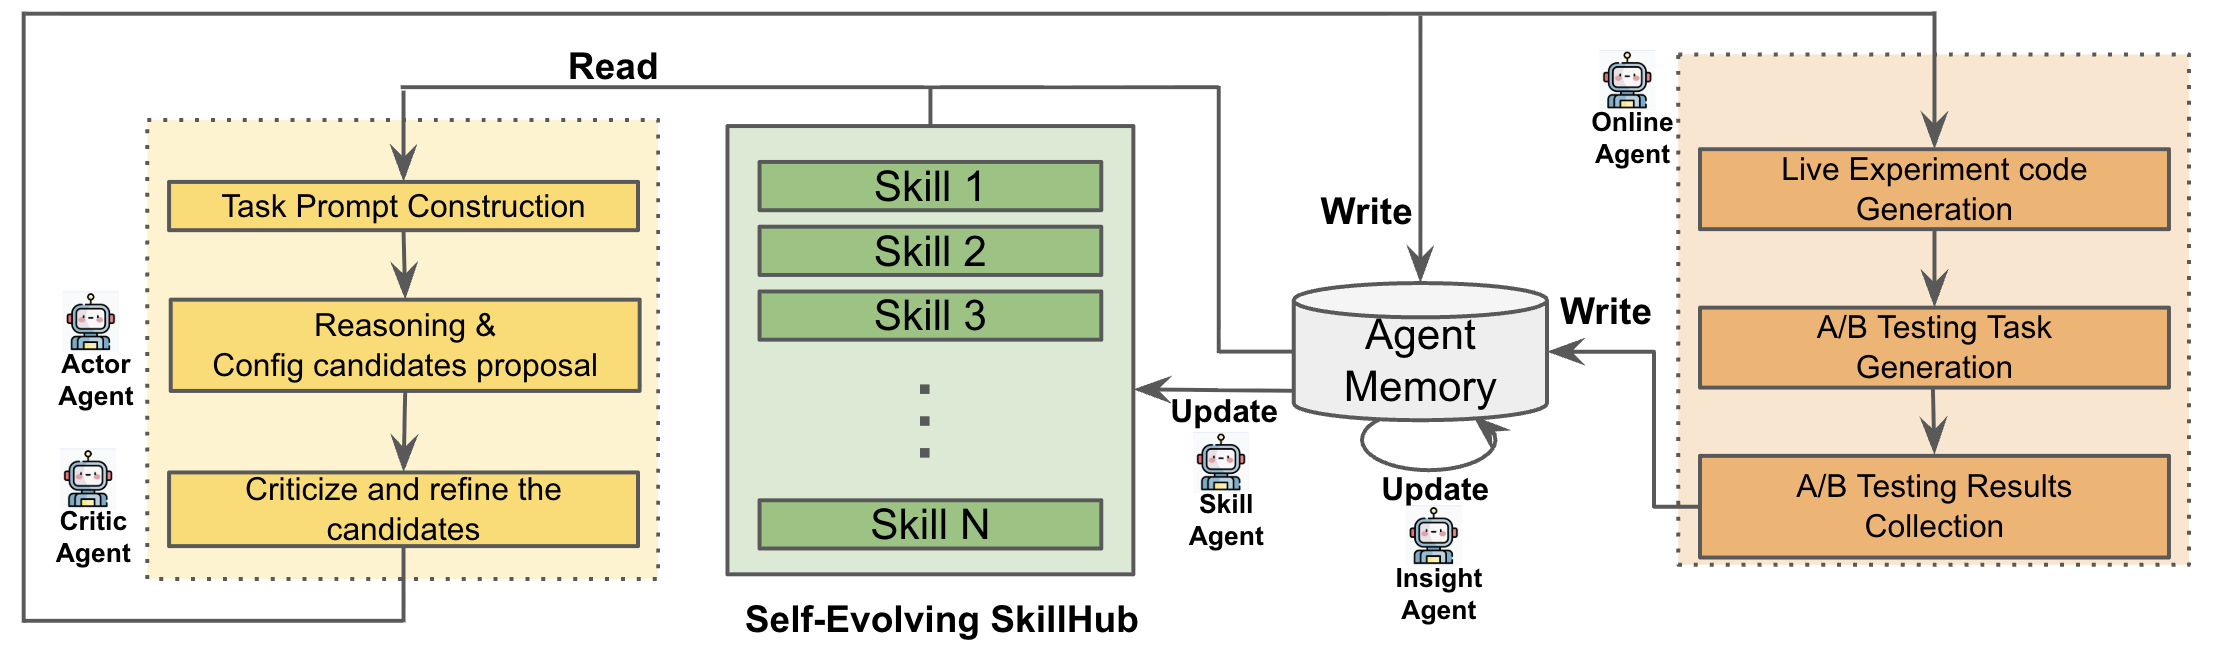
The original figure shows the multi-agent optimization loop. From the original paper; copyright remains with the authors.
Core equation
Reported results
Live A/B, p<0.05. Value-based retrieval/pre-ranking Engagement1/Engagement2/Diversity +0.75%/+0.90%/+0.48%; fusion/ranking +0.62%/+0.19%/+0.06%; diversity/reranking +0.21%/+0.29%/+3.43%.
Local reproduction
Three rounds with up to nine ranking genomes each, validation-only Critic and isolated final test. Champion transition/content/diversity 0.30/0.35/0.35. Versus fixed manual recipe, Hit@10 +8.33%, NDCG@10 +17.34%, fresh Hit@10 +150%. Metrics. Local executable weights, not Google's scheduling API or online agent.