Learning What to Remember: Test-Time Training via Context Distillation
Core fixed-context NumPy mechanism, not full training or kernel performance.
Paper information
| Field | Details |
|---|---|
| Paper | Paper or original source |
| Institution | Princeton University; first author Zixuan Wang. |
| First public release | 2026-08-03 (arXiv v1) |
| Author code | dangxingyu/ttcd. |
| Local adapter or method key | ttcd |
| Local reproduction code | src/auto_research/reproductions/ttcd/ |
Paper method and evidence
A long-window teacher supervises short-window student fast weights through hidden-state differences, retaining information useful later.
flowchart LR
  A[Long-window teacher] --> B[Hidden-state difference]
  B[Hidden-state difference] --> C[Train short-window fast weights]
Original paper figure
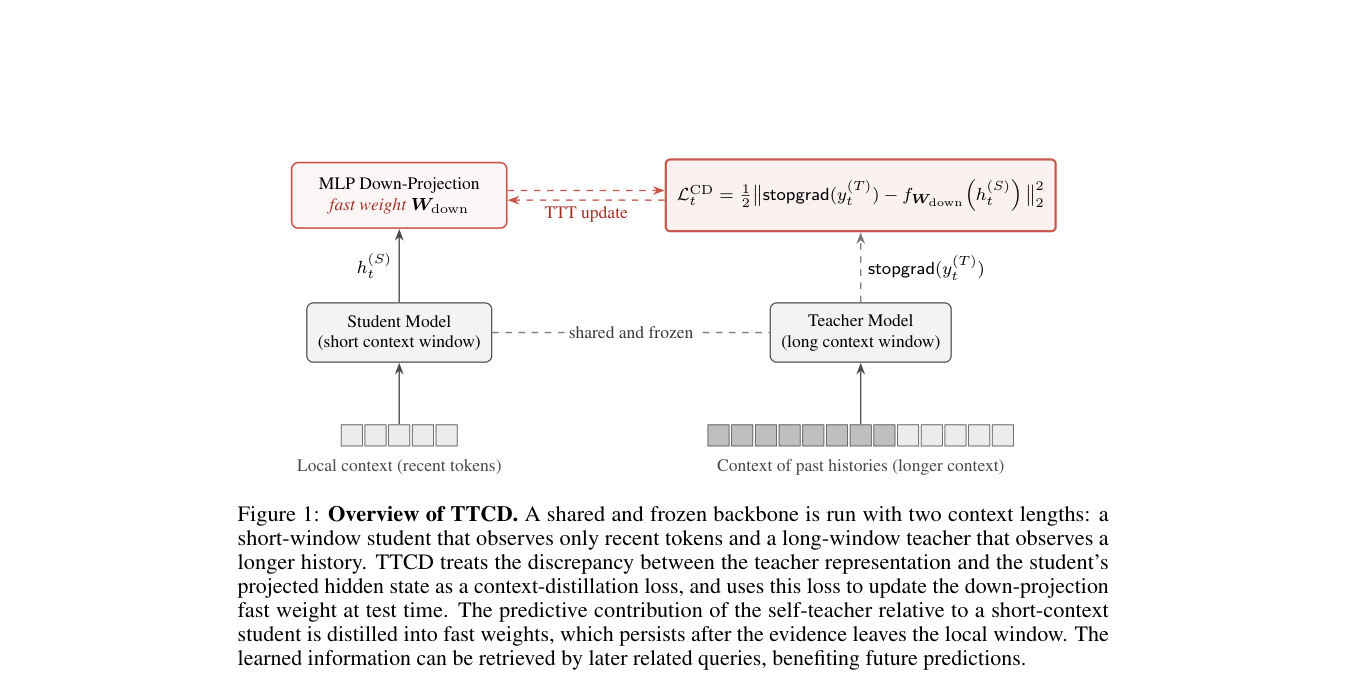
Figure shows distillation into fast weights. From the original paper; copyright remains with the authors.
Core equation
\[
\mathcal L_{TTCD}=\sum_t\lVert h_t^{long}-h_t^{fast}\rVert_2^2
\]
Reported results
IP-TTCD outperforms DeltaNet, Gated DeltaNet, sliding-window attention and TTT in the paper's long-context LM experiments.
Local reproduction
Same 64 examples and seed, recent-window attention 0.0781, TTCD 0.8594, +78.12 percentage points.
Fixed metrics. Batch index. No original checkpoint, CUDA kernel or full benchmark.