DME: Douyin multimodal embeddings for scalable retrieval and fine-grained semantics
Core public-data mechanisms, not Douyin production.
Paper information
| Field | Details |
|---|---|
| Paper | Paper or original source |
| Institution | ByteDance / Douyin. |
| First public release | 2026-08-03 (arXiv v1) |
| Author code | No official author code linked by the paper as checked on 2026-08-09. |
| Local adapter or method key | dme |
| Local reproduction code | src/auto_research/reproductions/dme/ |
Paper method and evidence
Contrastive vector retrieval is efficient but coarse; explicit CoT is too expensive online. After contrastive pretraining, organize evidence with Evidence-Grounded Typed Latent Reasoning and preserve opposite-side details with Cross-Conditional Reconstruction. Both generation heads are training-only.
flowchart LR
  A[Contrastive pretraining] --> B[Organize typed latent evidence]
  B[Organize typed latent evidence] --> C[Train cross-conditional reconstruction]
  C[Train cross-conditional reconstruction] --> D[Serve embedding only]
Original paper figure
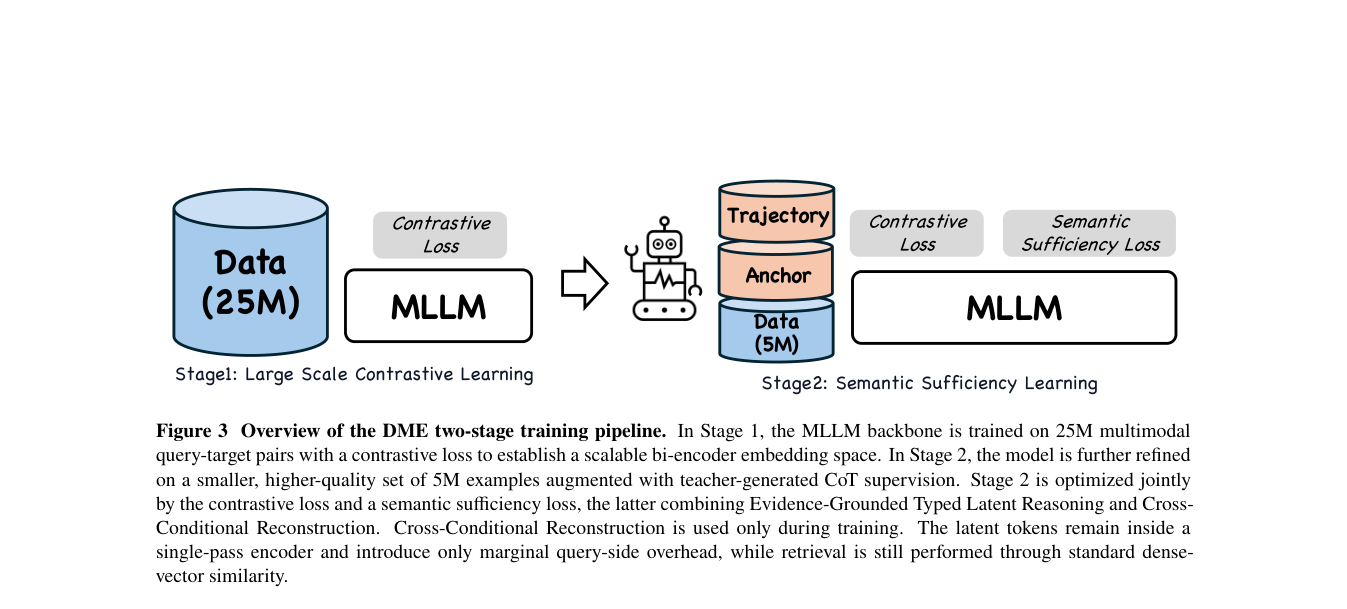
The original figure shows latent evidence and reconstruction. From the original paper; copyright remains with the authors.
Core equation
Reported results
MMEB-v2 2B/9B scores 74.8/78.4; internal offline +2.92%, search A/B Lifetime +0.1%. Deployed for generation, image search, and AI search.
Local reproduction
On MovieLens-100K 260 users/420 items, seed 42, shared transition+content vs typed latent evidence and bidirectional ridge reconstruction, with zero serving generation heads: NDCG@10 0.0354→0.0323 (-8.84%). Metrics. No 2B/9B backbone, private data or billion-scale index.