Math-Shepherd: Process rewards without manual step labels
Core mechanism diagnostic; not the original 7B/13B benchmark.
Paper information
| Field | Details |
|---|---|
| Paper | Math-Shepherd (arXiv 2312.08935) |
| Institution | Peking University / Alibaba Group. |
| First public release | 2023-12-14 (arXiv v1) |
| Author code | No standalone author repository found or released. |
| Local adapter or method key | math-shepherd |
| Local reproduction code | src/auto_research/post_training/ |
Paper method and evidence
Sample several continuations from an intermediate reasoning step. Their final answer correctness supplies automatic step labels for verifier training and reranking.
flowchart LR
  S[Intermediate step] --> C[Sample continuations]
  C --> V[Verify final answers]
  V --> L[Derive step labels]
  L --> R[Train verifier and reranker]
Original paper figure
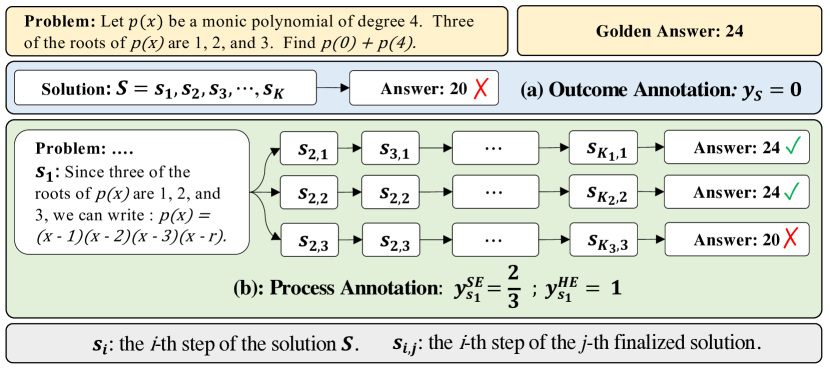
The original figure shows automated step labels. From the original paper; copyright remains with the authors.
Core equation
Reported results
The paper improves generation and reranking of several 7B/13B models on GSM8K and MATH. No production A/B.
Local reproduction
Arithmetic candidates, 120 steps, 256 examples, seed 42: 0.2344→0.6250 (+166.67%) with matched reward, KL, length and candidate budgets.
auto-research post-train --algorithm math-shepherd --dataset arithmetic-smoke --maximum-examples 256 --steps 120 --seed 42
auto-research evolve --model post-training --dataset arithmetic-smoke --direction "Combine math-shepherd with installed paper operators" --generations 2 --population 4
Fixed-seed metrics. Only the method-specific objective, state updates and matched budget are tested. No large model, multi-GPU RL, private environment, live web or full benchmark.