M6-Rec: Turning a pretrained language model into an open-ended recommender
Fidelity: core mechanism reproduction. Frozen pretrained backbone, natural-language behavior, option prototypes and per-layer bottleneck adapters. Private data, production M6 and serving optimizations are not reproduced.
Paper information
| Field | Details |
|---|---|
| Paper | Paper or original source |
| Institution | Alibaba |
| First public release | 2022-05-17 (arXiv v1) |
| Author code | No official author code identified (checked 2026-08-09). |
| Local adapter or method key | m6rec |
| Local reproduction code | src/auto_research/reproductions/m6rec/ |
Paper method and evidence
Separate retrieval, ranking, explanation and dialogue architectures are expensive to maintain. M6-Rec serializes anonymous behavior and candidates in natural language, supporting ranking, retrieval, zero-shot inference, explanations, content generation and dialogue. Option tuning and per-layer option adapters update around 1% task parameters rather than fully fine-tuning M6. Late interaction, early exit, sharing and pruning yield 10M/2M M6-Edge models.
flowchart LR
  A[Natural-language behavior and item] --> B[Frozen pretrained backbone]
  B[Frozen pretrained backbone] --> C[Option prototypes and layer adapters]
  C[Option prototypes and layer adapters] --> D[Task scores]
Original paper figure
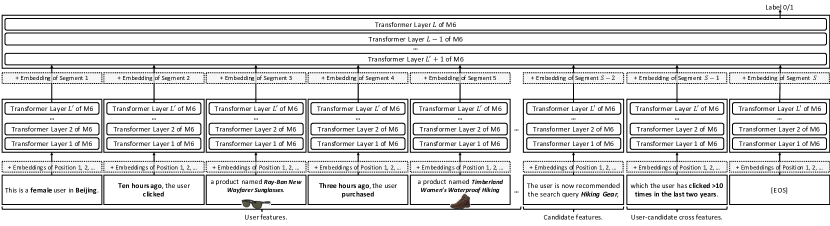
Figure 3 shows the main method components. From the original paper; copyright remains with the authors.
Core equation
For task \(t\), freeze backbone \(\Theta\) and optimize option \(O_t\) and layer adapters \(A_t^l\). The local binary classifier compares the normalized representation to two trainable prototypes.
Reported results
| Task | Production baseline | M6-Rec |
|---|---|---|
| AlipayQuery CTR AUC | DIN 0.7332 | 0.7508 |
| TaoProduct CTR AUC | DIN 0.7611 | 0.7995 |
| AlipayMiniApp HitRate@100 | TwinBERT 69.6% | 74.1% |
| Unseen mini-app HitRate@100 | TwinBERT 49.6% | 57.0% |
The online Alipay mini-app comparison reports >+1.0% relative CTR vs a TwinBERT-style dual tower and full rollout from July 2021.
Local reproduction
Frozen pretrained prajjwal1/bert-tiny (4.4M parameters) models histories of previously liked titles/genres and the candidate, split chronologically by user. Option-only trains two prototypes (256 parameters); option-adapter trains them plus two 24-dimensional adapters (12,848 parameters). Three seeds each use 4,000 train/1,000 test and 80 steps.
| Arm | AUC mean ± SD | Relative lift |
|---|---|---|
| Option only | 0.53832 ± 0.01724 | — |
| Option-adapter | 0.53890 ± 0.01516 | +0.12% ± 0.41% |
Per-seed relative changes are −0.36%/+0.07%/+0.65%. A weak positive mean with variance is not stable industrial lift. This is an incremental adapter ablation, not a comparison against DIN. Stable metrics. Model cache, data and runs remain Git-ignored; no checkpoint is committed.